An Autonomous AI Financial Blogger & Newsletter Engine
A 115-node, fully autonomous n8n pipeline that researches, writes, illustrates, and publishes a daily voice-driven financial blog post to Ghost — entirely on self-hosted infrastructure, with zero human input.
THE BRIEF
What the system needed to do.
This project is a fully autonomous, self-hosted content engine that publishes one original financial blog article every day with no human writer in the loop. Built as a 115-node n8n workflow across seven chained flows, it scores trending keywords against eight ETF profiles, discovers and virality-ranks YouTube videos, editorially selects the strongest story, and assembles a fact-checked knowledge base using Jina, Cohere embeddings, and a self-hosted Qdrant vector store. A voice-driven AI writer then produces a thesis-led article in Ghost block format, auto-sources and visually vets imagery, and publishes a members-only post with newsletter dispatch — all on owner-controlled infrastructure.
The scope
Build a fully autonomous, self-hosted pipeline that researches, writes, illustrates, and publishes a daily financial blog post with zero human input.
DESIGN CHOICES
What makes the build interesting.
Retail ETF & income investors
End-to-end autonomy across seven chained flows
RAG-grounded, fact-checked writing
Vision-based image curation
THE ARCHITECTURE
Follow the flow.
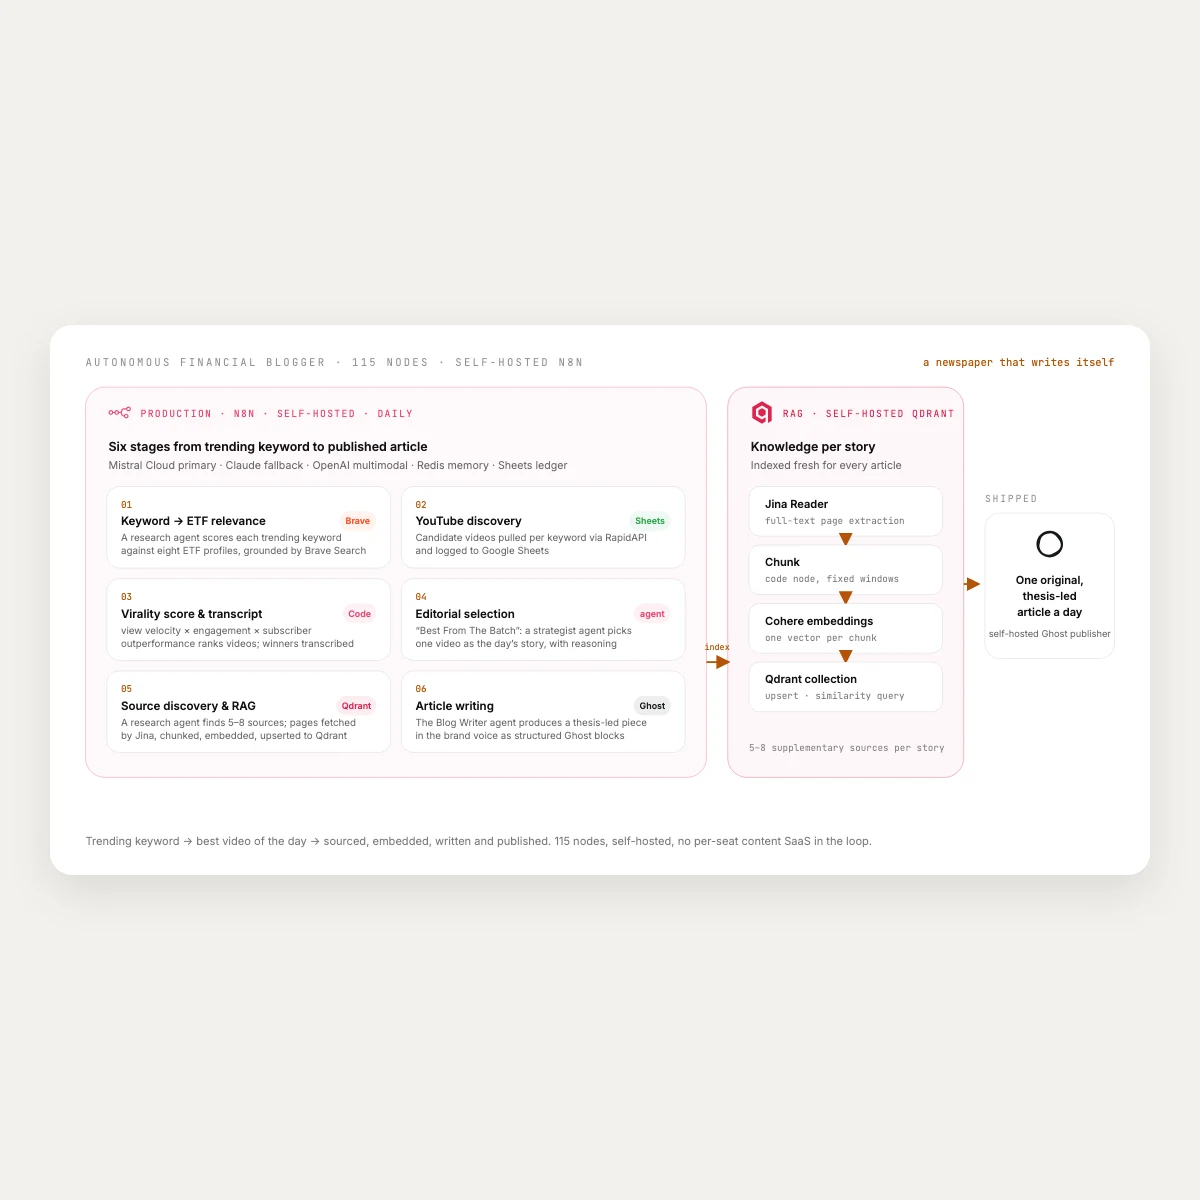
- Keyword-to-ETF relevance scoring — research agent scores each trending keyword against all eight ETF profiles (YES/NO + justification), grounded by live Brave Search.
- YouTube video discovery — candidate videos are pulled per keyword via RapidAPI and logged to Google Sheets.
- Virality scoring & transcription — a custom score (view velocity × engagement × subscriber outperformance) ranks videos, and winners are transcribed.
- Editorial selection ("Best From The Batch") — a strategist agent selects exactly one video as the day's story, with reasoning for every candidate.
- Source discovery & RAG indexing — a research agent finds 5–8 supplementary sources; pages are fetched (Jina), chunked, embedded (Cohere), and upserted to a self-hosted Qdrant collection.
- Article writing — the Blog Writer agent produces an original, thesis-led piece in the brand voice, output as structured Ghost content blocks.
- Image sourcing, vetting & Ghost publishing — image placeholders are resolved via Brave search and a vision-based AI editor, then the assembled post is published to Ghost as a members-only article with newsletter dispatch.
Tools and platforms
- n8n — workflow orchestration (115 nodes, self-hosted)
- Ghost — publishing CMS (via custom self-hosted publisher endpoint)
- Qdrant — self-hosted vector database (RAG knowledge base)
- Cohere — text embeddings
- Jina Reader — full-text web page extraction
- Brave Search — live web search (text & image)
- Mistral Cloud — primary LLM for several agents
- Anthropic Claude — fallback / high-reasoning LLM
- OpenAI — chat model (multimodal image evaluation & parsing)
- Redis — chat memory backing for agents
- Google Sheets — orchestration spine, status ledger & audit trail
- RapidAPI (YouTube) — video search, channel details & transcription
- SerpAPI — supplementary search results
- Structured Output Parsers — schema-enforced agent outputs
What the design enables.
- Total data sovereignty and cost control — running self-hosted on owner infrastructure (n8n, Qdrant, Ghost publisher) eliminates per-seat SaaS fees, vendor lock-in, and the need to send strategy data to third-party platforms.
- Commercially aware, not spammy — strict YES/NO ETF relevance scoring ensures funds are mentioned only when there's a genuine, defensible connection, protecting editorial credibility while still driving product awareness.
- Resilient and observable by design — modular flows with multi-model fallbacks (Mistral → Claude), Redis-backed chat memory, and a Google Sheets status ledger mean failures are isolated, retryable, and fully auditable.
The difficult parts.
- AI hallucinating financial statistics. Citing made-up numbers in finance is a credibility killer. We solved it with a retrieval-augmented architecture — Jina-fetched sources are chunked, Cohere-embedded, and stored in Qdrant, so the writer queries a verified knowledge base and is explicitly forbidden from inventing data.
- Forced, unconvincing product mentions. Early outputs shoehorned ETFs into unrelated topics. We introduced a dedicated relevance-scoring agent calibrated to err toward "NO," gating every fund mention behind a paragraph-level "could a writer actually defend this?" test.
- Selecting professional imagery automatically. Text-only image search returned memes and watermarked stock. We added a vision-capable AI editor that visually reviews each candidate thumbnail against the alt-text intent and rejects anything unfit for a financial publication, declining to force a pick when nothing qualifies.
Build notes and context.
The brief: a newspaper that writes itself.
The client runs a financial blog with a distinct personality — contrarian, evidence-driven, and unafraid to tell readers when the mainstream take is wrong. The challenge was deceptively simple to state and brutally hard to deliver: publish one original, fully-researched, illustrated article every single day, in a consistent editorial voice, without a human writer touching the keyboard. The output also had to do commercial work — naturally surfacing the eight ETFs the business cares about, but only when the connection was genuine, never as forced product placement.
We architected the solution as a 115-node n8n workflow split into seven discrete, chained flows, each owning one stage of the editorial supply chain. This modular design was a deliberate choice: a monolithic "do everything" agent would have been impossible to debug, expensive to run, and prone to compounding errors. By breaking the pipeline into independent flows connected via internal webhooks, each stage could be tested, retried, and reasoned about in isolation.
Flow 1 — Keyword-to-ETF relevance scoring. Before any writing happens, an AI research analyst (running Mistral with a Claude fallback, augmented by live Brave Search) cross-references each trending keyword against all eight ETF profiles. It returns a strict YES/NO verdict per fund, with a self-contained justification on every YES. Crucially, it's calibrated to err toward NO — false positives downstream waste compute and produce unconvincing copy, so the bar for "relevant" is a paragraph a writer could actually defend.
Flows 2–5 — Discovery, scoring, and editorial selection. The pipeline pulls candidate YouTube videos (via RapidAPI), then computes a custom virality score blending view velocity, like-to-view engagement ratio, and subscriber outperformance — a proxy for "what the investing public actually cares about right now." Winning videos are transcribed, and a senior-editorial-strategist agent then picks exactly one video as the day's story, judged on timeliness, article potential, originality of angle, and breadth of appeal.
Flow 6 — Source discovery and RAG. This is where the blog's contrarian, evidence-first ethos really shows. A research agent runs 4–6 targeted searches to find 5–8 high-quality supplementary sources — hard data, opposing viewpoints, primary documents, and ETF-specific context — filtered through a Tier 1/2/3 source-quality hierarchy that prioritises Bloomberg, Reuters, the Fed and SEC filings over low-signal blogs. Selected pages are fetched full-text via Jina Reader, cleaned and chunked, embedded with Cohere, and upserted into a self-hosted Qdrant vector collection — giving the writer a fact-checked knowledge base to query rather than hallucinate against.
Flow 7 — Writing, illustration, and publishing. The Blog Writer agent transforms the transcript into an original article — not a summary — built around a single thesis, written in the blog's signature conversational-but-rigorous voice, and output as a structured array of Ghost content blocks. Image placeholders are then fanned out, candidate images sourced via Brave image search, and a vision-capable AI image editor visually reviews thumbnails to pick the single most professional, on-topic image per slot. Finally, the assembled post is published to Ghost via a custom self-hosted publisher endpoint as a members-only article, with the newsletter dispatch flagged on in the same call.
The result is a genuinely autonomous editorial operation. Every morning, the system independently decides what's worth writing about, what the data actually says, how to argue it in a distinctive voice, and how to illustrate and distribute it — running entirely on infrastructure the owner controls. Google Sheets acts as the orchestration spine and audit trail (status flags track each article's journey), so the owner retains full visibility and the ability to intervene at any stage without ever being required to.
Have a related process in mind?
Tell me what goes in, what should come out and where the current process gets stuck.