Human in the Loop vs Human on the Loop: Where to Put the Gate
The article defines human in the loop as a synchronous approval pause and human on the loop as asynchronous supervision, compares them across role, latency, risk, and audit needs, and introduces a reversibility and blast-radius test to assign gates per action. It outlines how to graduate from blocking approval to monitored autonomy and how to build those gates, exception queues, and audit trails in n8n.
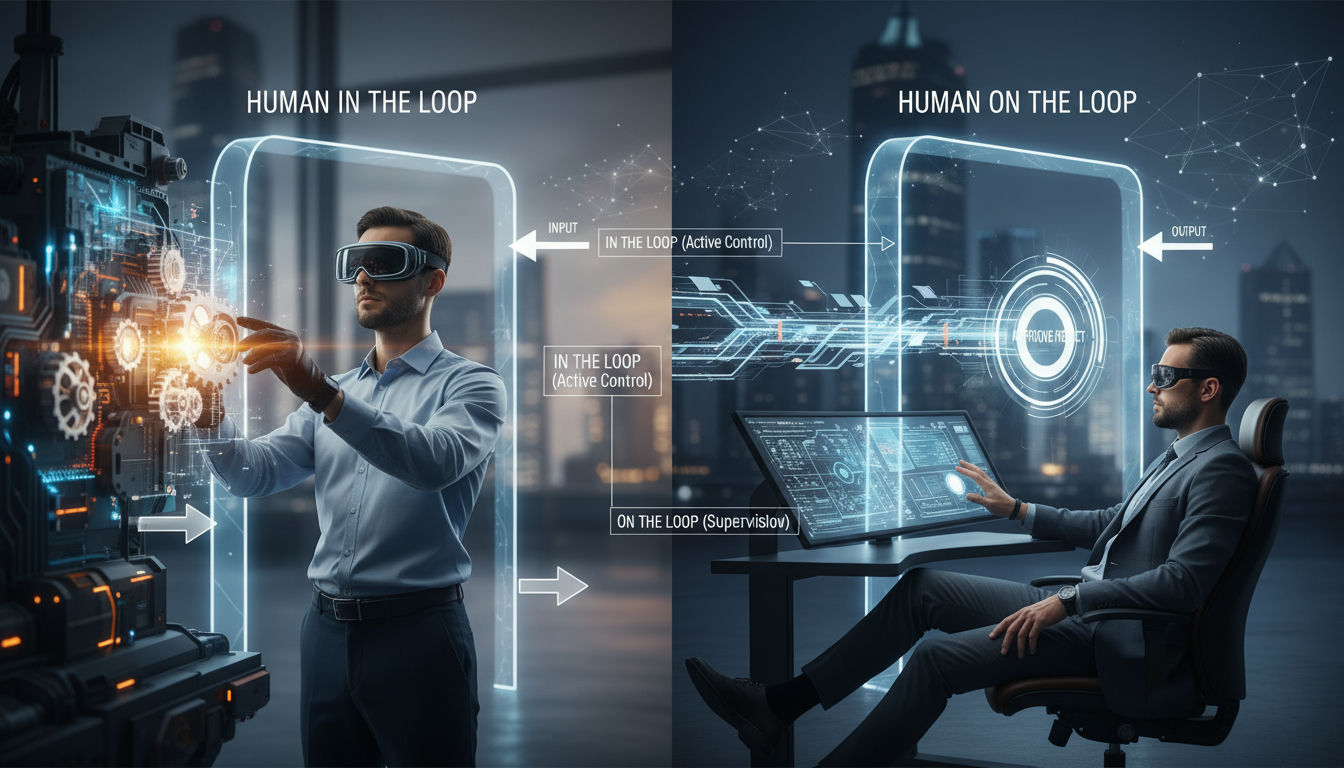
Human in the Loop vs Human on the Loop: The Core Difference
Human in the loop vs human on the loop is the choice in an AI workflow between a synchronous approval gate and asynchronous supervision: human in the loop means a person must actively approve an action before it executes, while human on the loop means the system acts autonomously while a person monitors and intervenes only on exceptions.
The shorthand teams use makes the difference clear. In the loop you are the gatekeeper, execution pauses and waits for your yes or no. On the loop you are the supervisor or lifeguard, watching the flow, stepping in only when something drifts off track.
Neither mode is universally better. A single workflow can and often should use both, applying the stricter gate where mistakes are hard to undo or costly to contain, and the lighter supervisory layer where speed and volume matter more than perfect control point by point.
With the definitions settled, the next question is how to tell them apart across every dimension that matters for a real workflow.
HITL vs HOTL Side by Side: Role, Execution, Risk, and Audit Trail
n8n operationalized this choice as a workflow pause that routes an explicit approve/deny prompt to Slack, Telegram, or email before a tool executes, while its asynchronous counterpart lets the AI execute inside policy limits and only surfaces exceptions. The table below sorts the two modes by role and risk so you can decide action by action which one applies.
| Criterion | Human-in-the-Loop (HITL) | Human-on-the-Loop (HOTL) |
|---|---|---|
| Human's role | Co-pilot: approve, modify, or deny first | Lifeguard: monitors and overrides exceptions |
| Execution timing | Synchronous: workflow pauses until a person decides | Asynchronous: AI executes, human reviews concurrently |
| Typical latency added | Reviewer-dependent; minutes to hours | Near-zero routine; latency only on exceptions |
| Primary benefit | Prevents irreversible or regulated mistakes | Preserves throughput; scales to high volume |
| Primary drawback | Throughput ceiling set by reviewer capacity | Missed drift if alerts are weak |
| Audit/logging requirements | Log reviewer identity, timestamp, parameters, outcome | Log execution trace, policy threshold, exception trigger |
| Best-fit use cases | High-stakes, regulated, novel-domain decisions | High-volume, low-risk, clear policy boundaries |
HITL works like a co-pilot. The human sees the actual proposed action that pauses and waits for a person to take approve or deny, including which tool the agent wants and with what parameters, and must approve, edit, or deny before the workflow resumes. That co-pilot view is intentionally blocking.
HOTL works like a lifeguard or supervisor. The human does not see every transaction, but watches a stream where AI executes within policy limits and the person supervises exceptions, stepping in from a dashboard or alert when confidence is low, a threshold is crossed, or output looks off. That supervision is non-blocking by default.
HITL and HOTL are not competing philosophies. They're settings you choose per action, not per system.
Choosing the Right Gate: A Reversibility and Blast-Radius Test
Should this AI action require human-in-the-loop approval before it runs, or is human-on-the-loop supervision enough? Content, data, and e-learning operations teams decide per action by asking three operational questions: can the action be undone easily, how far can a mistake spread, and can a person verify the output quickly enough for a synchronous gate to work.
Knowing which criteria separate a gate from a dashboard matters once it's applied to real actions, so here's how that plays out stage by stage.
The practical test most teams use is a three-question check: can it be undone, how far can a mistake spread, and can you verify it quickly. That maps directly to gate design because blast radius and reversibility decide what the agents absorb and what reaches a human.
The three questions in practice
- Can it be undone? If reversal requires external recall, refunds, or manual cleanup, bias toward a gate. If it is a draft saved or a label applied internally, supervision is often enough.
- How far can a mistake spread? One record versus ten thousand records, one user versus a public feed, changes the tolerance. Wide replication pushes toward in-the-loop or on-the-loop with hard volume and value limits.
- Can you verify it fast? A gate only works if a reviewer can judge the output from clear evidence in seconds to a few minutes. If verification needs deep reconstruction, do not pretend synchronous approval is happening; use monitoring and sampling.
Applied to named stages
Publishing a drafted article. Typically human-in-the-loop. Reversibility is low once URLs are cached, syndicated, or sent by email. Blast radius is wide. Verification is fast when title, body, and metadata are shown together, so a pause for approval is practical.
Sending a financial data extract. Typically human-in-the-loop. An extract shared externally cannot be recalled cleanly, and one wrong file affects downstream analysis and compliance. Verification needs spot checks against source systems, which justifies holding the send for review.
Grading or certifying e-learning submissions. Split decision. Routine quiz grading and formative feedback can run human-on-the-loop with exception review. Issuing a final certificate or official pass/fail goes human-in-the-loop: low reversibility, reputational and regulatory blast radius, and quick human judgment on borderline cases.
Updating a production database record. Typically human-in-the-loop for customer data or bulk writes. Even when technically reversible, rollback is costly and errors propagate to billing, search, and recommendations. Verification is possible but slow, so gate it.
Sending customer-facing communications. Typically human-in-the-loop. Delivery is irreversible, blast radius includes brand trust and opt-out compliance, and verification is rapid when the final message and audience slice are previewed.
Once a team has sorted its actions this way, the next question is how those gates evolve as the system proves itself.
From Full Approval to Supervised Autonomy: Earning the Right to Loosen the Gate
The maturity curve from human-in-the-loop to human-on-the-loop is earned, not assumed: teams keep new agent actions fully blocking until measured evidence justifies moving them to monitored autonomy.
The stage-by-stage sorting above sets a starting point. The harder discipline is deciding when and how to loosen a gate once it's earned trust. The mistake teams make is flipping a reliable-looking workflow to human-on-the-loop after a few good runs, without a defined evidence bar. That turns oversight into a rubber stamp and hides drift until customers notice.
Graduation should rest on three kinds of evidence gathered in production, not in a demo. First, agreement: the AI proposal matches what the human would have approved, repeatedly, across a range of diverse cases. Second, stability over time: a sustained period with no flagged exceptions, policy violations, or post-action corrections. Third, measured error and rejection rates that stay within your pre-defined tolerance for that action class. DeepScribe frames this feedback loop as continuous learning, where human involvement refines accuracy over time, which only works if you keep measuring it.
To justify loosening, you need an audit trail that lets you reconstruct any decision. That means append-only logs of proposal payload, context presented to the reviewer, reviewer identity and decision, timestamp, final executed action, and post-action verification outcome. As StackAI notes, you start supervised, then graduate to exception-only or sampled approvals once metrics prove reliability, and you must always be able to show who approved what, when, and why.
Define rollback triggers before you graduate: a rising rejection rate, an exception queue breach, a failed post-action verification, or detection of sensitive-data or anomalous parameters. When a trigger fires, the workflow automatically reverts that action class to full blocking approval and holds for review, restoring the gate until you have new evidence it is safe again.
Building the Gate in n8n: Approval Nodes, Exception Queues, and Where the Architecture Fits
In n8n, a human-in-the-loop gate is a built-in pause: when an AI Agent tries to use a tool marked for review, the workflow pauses and waits for a person to approve or deny before that tool runs. The pause triggers an approval request through your configured channel: Slack, Telegram, n8n Chat, email, Discord, Teams, WhatsApp, Google Chat or Outlook.
AI-powered content systems and workflow automation built around your team’s tools, processes, and goals—designed, implemented, and maintained by a Cambridge-trained automation engineer.
That graduation logic is easy to state in principle. The real test is what it looks like wired into an actual pipeline.
A synchronous HITL gate is implemented as an Agent Tool panel > Human review step > connected tools. The agent determines it needs a gated tool, the execution stops, and the reviewer gets a message built from $tool.name and $tool.parameters, the exact tool name and the AI-generated inputs it wants to use. Approve, and the tool executes with that input; deny, and the call is canceled and the AI is told it was rejected, so your system prompt needs explicit denial handling.
An asynchronous HOTL layer looks different. Instead of pausing every run, the workflow finishes, but edge cases route to an exception queue. In practice that means a separate branch: IF confidence < threshold or validation fails → write to a Supabase/Postgres table + Slack alert + dashboard row; ELSE proceed. You review only the queue, not every execution.
Where the gate sits matters. In a content-publishing pipeline, place the synchronous gate after draft and fact-check but before the Webflow/WordPress publish node. In a financial-research pipeline, put it before any irreversible action the docs call out (sending external communications, modifying records, or deleting data) or after extraction, to verify tickers and numbers before write.
For audit, log the triad the reviewer actually saw: $tool.name, $tool.parameters as JSON, channel, timestamp, and approver identity. When you own self-hosted or cloud-based infrastructure, you own that webhook endpoint, the Slack signing secret, and the execution logs, so you are not waiting on a third party to expose who approved what. One example of this architecture in production is Hesham Mashhour - AI Content Systems: AI agents given defined tasks, limits, and approval workflows, with exception handling that surfaces edge cases for human review, built around tools like n8n and Cloudflare.
With the architecture mapped out, the last question is how to actually decide, for your own workflow, where each gate belongs.
Putting It Together: A Quick Audit for Your Own Workflow
Your team is staring at an automation that can run end-to-end without anyone touching it, and the call you have to make is which steps still need a hard human approve before they run. Human in the loop vs human on the loop is not a system-wide philosophy you pick once, it is a mode you assign action by action based on risk and reversibility.
Run a 30-minute self-audit:
- List every outbound action. Not the triggers, not the data transforms, only the places your workflow creates, sends, deletes, spends, or publishes something to the outside world.
- Score each action with three questions. Can you undo it cleanly and completely? If it fails silently, how many records, customers, or downstream systems does it touch? How quickly could a person spot the error with the context they have?
- Tag the gate. If an action is irreversible, has high blast radius, and is hard to verify fast, it stays human-in-the-loop indefinitely. If it is reversible, low-blast, and easy to verify after the fact, it is a candidate for human-on-the-loop now, or after a short observed trial.
The point is not to be more cautious or more automated. The point is to stop treating oversight as all-or-nothing and to assign the right mode per action, then revisit that assignment as you collect real evidence from production.
This week, export your workflow's action list into a sheet and add three columns for those questions. Fill it in with your ops lead. That one page becomes your gate map, and your record for why each gate is where it is.
Sources (7)
- Human-in-the-loop for tools | Build | n8n Docs
- Human-in-the-Loop vs. Human-on-the-Loop: When to Use Each for Enterprise Workflows
- Human in the Loop vs. Human on the Loop: How to Choose for AI Agents
- Human in the Loop vs Human on the Loop: Where the Reviewer Sits in an Agent-Run SDLC
- Guide to Optimizing Human AI Collaboration Systems
- Human-in-the-Loop AI Agents: How to Design Approval Workflows for Safe and Scalable Automation - StackAI · AI Agents for the Enterprise
- Human-in-the-loop for tools | Build | n8n Docs
Frequently Asked Questions
What happens if no one responds to an approval request in n8n?
In n8n the workflow pauses and waits for a person to take Approve or Deny before the tool executes, so it will stay paused until someone acts. Build a timeout branch, escalate to a second channel, or auto-deny after a set window and tell the agent how to handle the rejection.
Can I use both HITL and HOTL inside the same workflow?
Yes. The pattern is to tag per action, not per workflow. Keep sending messages, modifying records, or deleting data as blocking HITL gates, while low-risk transforms run under HOTL where AI executes within policy limits and a person supervises exceptions.
What should I show a reviewer to make approval fast and safe?
Show the exact request the agent wants, not a summary. n8n exposes this as a message built from $tool.name and $tool.parameters so the reviewer sees which tool and with what parameters. Add the final rendered preview and the source check that justifies the decision.
Which chat tools can I use for human approvals?
n8n can send the approve/deny prompt to Slack, Telegram, email, Teams, WhatsApp, Discord, Google Chat, Outlook and also Slack, Telegram, or the n8n Chat interface. Pick the channel where your reviewer already works and log channel, approver, and timestamp for audit.
When is it actually safe to graduate an action from HITL to HOTL?
Use the proven path to start supervised, then graduate to exception-only or sampled approvals once metrics prove reliability. Track agreement with human decisions, stability over weeks, and rejection rates against a pre-set tolerance before loosening the gate.
What needs to go into the audit trail for human review?
At minimum keep who approved what, when, and why plus the fuller record of who reviewed, timestamp, what they approved or modified, and downstream outcome as described in this HITL vs HOTL guide. Store proposal payload, context shown, decision, and final executed result in append-only logs.
How does a human-on-the-loop exception queue work in practice?
HOTL means AI executes within policy limits; person supervises and steps in on exceptions. In code that is an IF branch: if confidence is low or validation fails, write to a review table and send an alert; otherwise continue. You only review the queue, not every run.
What happens after a reviewer clicks Deny?
The tool call is canceled and the agent is told it was rejected, so the workflow does not execute that action. Your system prompt must handle denial gracefully, for example by asking for corrected inputs, choosing an alternative tool, or closing the task.